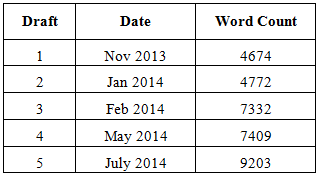Showing posts with label science-and-engineering-paper-of-the-week. Show all posts

August 9, 2022

New Paper on Developmental Braitenberg Vehicles now live!


The special issue of Artificial Life on Embodied Intelligence is now live! Inside you will find our paper "Braitenberg Vehicles as Developmental Neurosimulation", which has lived on the arXiv since 2020. This paper lays out an approach to Developmental Neurosimulation, involving three adversarial approaches to the agent-based development of embodied brains and embodied cognition. Here is the abstract:

Connecting brain and behavior is a longstanding issue in the areas of behavioral science, artificial intelligence, and neurobiology. As is standard among models of artificial and biological neural networks, an analogue of the fully mature brain is presented as a blank slate. However, this does not consider the realities of biological development and developmental learning. Our purpose is to model the development of an artificial organism that exhibits complex behaviors. We introduce three alternate approaches to demonstrate how developmental embodied agents can be implemented. The resulting developmental Braitenberg vehicles (dBVs) will generate behaviors ranging from stimulus responses to group behavior that resembles collective motion. We will situate this work in the domain of artificial brain networks along with broader themes such as embodied cognition, feedback, and emergence. Our perspective is exemplified by three software instantiations that demonstrate how a BV-genetic algorithm hybrid model, a multisensory Hebbian learning model, and multi-agent approaches can be used to approach BV development. We introduce use cases such as optimized spatial cognition (vehicle-genetic algorithm hybrid model), hinges connecting behavioral and neural models (multisensory Hebbian learning model), and cumulative classification (multi-agent approaches). In conclusion, we consider future applications of the developmental neurosimulation approach.

There are many themes to follow up on in this paper. Just of few examples include:

* brain/body scaling in an embodied agent.

* the role of multisensory integration in the development of cognition.

* ways to classify shapes and motifs in the emergence of multi-agent collectives. 

* spatial cognition and transfer learning in developmental embodied systems.

Congratulations to Stefan Dvoretskii, Ziyi Gong, Ankit Gupta, Jesse Parent, and Bradly Alicea for their hard work.

December 22, 2017

Fault-tolerant Christmas Trees (not the live kind)

It's an interconnected Christmas scene, but that's not a Christmas Tree! (?) COURTESY: Andrew P. Wheeler.

This year's holiday season post brings a bit of graph-theoretic cheer. That's right, there is a type of network called a Christmas tree [1,2]! It is a class of fault-tolerant Hamiltonian graph [2,3]. So far, Christmas trees have been applied to computer and communications networks, but may be found to have a wider range of applications, particularly as we move into the New Year.


An example of a Christmas Tree directed graph as shown in [2]. The top two graphs are slim trees of order 3 (left) and 4 (right). A Christmas tree (bottom) includes selected long-range connections (longer than the immediate connection to mother, daughter, or sister nodes).

This tree could have used a bit more fault-tolerance!

NOTES:
[1] Hsu, L-H and Lin, C-K (2008). Graph Theory and Interconnection Networks. CRC Press, New York.

[2] Hung, C-N, Hsu, L-H, and Sung, T-Y (1999). Christmas tree: A versatile 1-fault-tolerant design for token rings. Information Processing Letters, 72(1–2), 55-63.

[3] Wang, J-J, Hung, C-N, Tan, J.J-N, Hsu, L-H, and Sung, T-Y (2000). Construction schemes for fault-tolerant Hamiltonian graphs. Networks, 35(3), 233-245.

May 10, 2017

Embryology Special Issue

Me and my colleagues are pleased to announce an upcoming special issue of the journal Biology (Basel). The topic is "Computational, Theoretical, and Experimental Approaches to Embryogenesis" (see announcement). Our view of what constitutes embryogenesis research is rather broad, spanning experimental studies, cellular reprogramming, bioinformatics, and artficial life. Therefore, we seek submissions from a wide variety of researchers and article types.


As the lead editor, I will take any questions you might have about interesting ideas, types of articles, or if you are interested in peer-review. As noted on the poster, the deadline for submissions is August 31, 2017. Looking forward to an excellent issue.

UPDATED (5/17):
With the initial dealine fast approaching, we have decided to extend the submission deadline to December 31. 

July 24, 2016

Catching up on Free Alife

Here are three Alife-related resources to catch up on, some new and some not yet posted to this blog:


Alife XV just concluded, and was hosted in Cancun by Carlos Gershenson and the Self-organizing Systems Lab at UNAM. The proceedings are available here.


Here are the Proceedings from the previous Alife conference (XIV), held in NYC during the Summer of 2014.


And here is the Spring 2016 issue of Artificial Life journal, which features selected papers from the Alife XIV conference (held in NYC in 2014). Be sure to check out the paper "An Informational Study of the Evolution of Codes and of Emerging Concepts in Populations of Agents", which I reviewed.

December 14, 2015

Klinotactic Thoughts and Holonomic Fun

What a week for models of movement! The first item is the most recent OpenWorm Journal Club (hosted on Google Hangouts and YouTube) called "Closing the Loop from Brain Cells to Behavior". This session explored the implications of two papers by Eduardo Izquirdo and Randall Beer [1] on C. elegans  Neuromechanics.


This work focuses on the existence of klinotaxis in C. elegans movement generation. Klinotaxis occur as small but important neural circuit generates movement signals in response to the environment. Specifically, sinusoidal movement of the head occurs as a function of central pattern generation in the brain and behavioral response to the environment.

The second item involves the BB8 droid from the upcoming Star Wars movie. As the first spherical rolling droid of the Star Wars metaverse, BB8 is also a very real mechanical prototype called the Sphero. And now you can build your own [2]! By capitalizing on a principle called holonomic motion, the body moves independently of the head, which balances on the rolling body. The following article (How does BB8 Work?) discusses the innovation and the details behind the patent registered by Disney Labs.


NOTES:
[1] Izquierdo, E.J. and Beer, R.D. (2015).  An integrated neuromechanical model of steering in C. elegans. Proceedings of ECAL, 199-206. MIT Press  AND  Izquierdo, E.J., Williams, P. and Beer, R.D. (2015).  Information flow through the C. elegans klinotaxis circuit. PLoS One, 10(10), e0140397.

[2] For more information, please see: Berkey, R.   Make your own Star Wars VII BB8 Droid. Nerdist blog, June 7 (2015)  AND  How does BB8 Work? http://www.howbb8works.com/

November 14, 2015

The Pace of Paper Construction

I recently found this graph amngst my files, having done this about a year ago to gauge the revisions of two papers [1, 2] published by myself and co-authors in 2014. The plotted function represents the number of words at a certain timepoint (draft completed every month). The plateaus represent a lack of development during that period.


[1] RED: Alicea, B.   Animal-oriented Virtual Environments: illusion, dilation, and discovery. F1000 Research, 3:202. doi: 10.12688/f1000research.3557.1 (2014).​

[2] BLUE: Alicea, B. and Gordon, R.   Toy Models for Macroevolutionary Patterns and Trends. Biosystems, 122, 25-37 (2014). Special Issue: Patterns of Evolution.

March 30, 2015

Causality, part II (was it caused by Part I?)

This post serves as a follow-up to a Synthetic Daisies post written in 2012 on new methods to detect causality in data.

Here are a few interesting readings at the intersection of data analysis and the philosophy of science. The first [1] is a new arXiv paper [2] that evaluates two approaches to evaluating causality using two machine learning techniques. A plethora of discriminative machine learning techniques have emerged in recent years to address relatively simple relationships. In terms of cause and effect itself, the distinguishing signal is often subtle and unclear even for seemingly obvious sets of relationships. In [2], techniques called Additive Noise Methods [3] and Information Geometric Causal Influence [4]. A dataset called CauseEffectPairs [5] was used to benchmark each method, and show that causal relationships can be uncovered from a wide variety of data.


The second paper (or rather series of papers) is on the topic of strong inference [6]. Strong inference is an alternative to hyper-reductionism and the use of over-simplified models. Strong inference involves the use of a conditional inductive tree to examine the possible causes for a given phenomenon [7]. Potential causes (or hypotheses) represent nodes of the tree, and these hypotheses are falsified as one moves through the tree using either inductive or empirical criteria. Unlike the machine learning models we discussed, the goal is to lead a researcher to key experiments that help to uncover the sources of variation. In general, this process of elimination lead us to the best answers, Yet according to Platt in [2], this approach can ultimarely provide us with axiomatic statements.

Conceptual steps involved in strong inference. COURTESY: Figure 1 in [8].

While this seems to be a fruitful methodology, it has turned out to be more inspirational than as a source of analytical rigor [9]. Strong inference hs inflenced a variety of scientific fields concentrated in the biological and social sciences. Platt predicted [2] that sciences that concurred with strong inference would be fields that experienced a greater number of breakthrough advances. However, in testing Platt's predictions regarding the efficacy of Strong Inference, is have been found that advances are not directly related to the adoption of the method [10]. This could be due to our incomplete understanding of the factors that drive scientific discovery and the rate of advancement. 


[2] Mooij, J.M., Peters, J., Janzing, D., Zscheischler, J., and Scholkopf, B.   Distinguishing cause from effect using observational data: methods and benchmarks. arXiv, 1412.3773 (2014).

[3] Hoyer, P.O., Janzing, D., Mooij, J.M., Peters, J., and Scholkopf, B.   Nonlinear causal discovery with additive noise models. In Advances in Neural Information Processing Systems (NIPS), 21, 689-696 (2009).

[4] Daniusis, P., Janzing, D., Mooij, J.M., Zscheischler, J., Steudel, B., Zhang, K., and Scholkopf, B. Inferring deterministic causal relations. In Proceedings of the 26th Annual Conference on Uncertainty in Artificial Intelligence (UAI), 143-150 (2010).

[5] This work was part of the CauseEffect Pairs Challenge and was presented at NIPS 2013.

[6] Platt, J.R.   Strong Inference: certain systematic methods of scientific thinking may produce much more rapid progress than others. Science, 146(3642), 347-352 (1964).

[7] Neuroskeptic   Is Science Broken? Let's Ask Carl Popper. Neuroskeptic blog, March 15 (2015).

[8] Fudge, D.S.   Fifty years of J.R. Platt's Strong Inference. Journal of Experimental Biology, 217, 1202-1204 (2014).

[9] Davis, R.H.   Strong Inference: rationale or inspiration? Perspectives in Biology and Medicine, 49(2), 238-250 (2006).

[10] O'Donohue, W. and Buchanan, J.A.   The Weaknesses of Strong Inference. Behavior and Philosophy, 29, 1-20 (2001).

August 26, 2014

Fireside Science: Fun with F1000: publish it and the peers will come

This content is cross-posted to Fireside Science. Please also see the update before the notes section.


For the last several months, I have been working on a paper called "Animal-oriented Virtual Environments: illusion, dilation, and discovery" [1] that is now published at F1000 Research (also available as a pre-print at PeerJ). This is a paper that has gone through several iterations, from a short 1800-word piece (first draft) to a full-length article. This includes several stages of editor-driven peer review [2], and took approximately nine months. Because of its speculative nature, this paper could be an excellent candidate for testing out this review method.

The paper is now live at F1000 Research.

Evolution of a research paper. The manuscript has been hosted at PeerJ Preprints since Draft 2.

F1000 Research uses a method of peer-review called post-publication peer review. For those who are not aware, F1000 approaches peer-review in two steps: the submission and approval by an editor stage, and the publication and review by selected peer stage. Let's walk through these.


The first step is to submit an article. For some articles (data-driven), they are published to the website immediately. However, for position pieces and theoretically-driven articles such as this one, a developmental editor is consulted to provide pre-publication feedback. This helps to tighten the arguments for the next stage: post-publication peer review. 

The next stage is to garner comments and reviews from other academics and the public (likely unsolicited academics). While this might take some time, the reviews (edited for relevance and brevity) will appear alongside the paper. The paper's "success" will then be judged on those comments. No matter what the peer reviewers have to say, however, the paper will be citable in perpetuity and might well have a very different life in terms of its citation index.

Why would we want to have such alternative available to us? Such alternative forms of peer review and evaluation can both open up the scope of the scientific debate and resolve some of the vagaries of conventional peer review [3]. This is not to say that we should strive towards the "fair-and-balanced" approach of journalistic myth. Rather, it is a recognition that scientists do a lot of work (e.g. peer review, negative results, conceptual formulation) that either falls through the cracks or does not get made public. Alternative approaches such as post-publication peer review is an attempt to remedy that, and as a consequence also serve to enhance the scientific approach.


COURTESY: Figure from [5].

The rise of social media and digital technologies have also changed the need for new scientific dissemination tools. While traditional scientific discovery operates at a relatively long time-scale [6], science communication and inspiration do not. Using an open science approach will effectively open up the scientific process, both in terms of new perspectives from the community and insights that arise purely from interactions with colleagues [7].

One proposed model of multi-staged peer review. COURTESY: Figure 1 in [8].

UPDATE: 9/2/2014:
I received an e-mail from the staff at F1000Research in appreciation of this post. They also wanted me to make the following points about their version of post-publication peer review a bit more clear. So, to make sure this process is not misrepresented, here are the major features of the F1000 approach in bullet-point form:

* input from the developmental editors is usually fairly brief. This involves checking for coherence and sentence structure. The developmental process is substantial only when a paper requires additional feedback before publication.

* most papers, regardless of article type, are published within a week to 10 days of initial submission.  

* the peer reviewing process is strictly by invitation only, and only reports from the invited reviewers contribute to what is indexed along with the article. 

* commenting from scientists with institutional email addresses is also allowed. However, these comments do not affect whether or not the article passes the peer review threshold (e.g. two "acceptable" or "positive" reviews).  


NOTES:
[1] Alicea B.   Animal-oriented virtual environments: illusion, dilation, and discovery [v1; ref status: awaiting peer review, http://f1000r.es/2xt] F1000Research 2014, 3:202 (doi: 10.12688/f1000research.3557.1).

This paper was the derivative of a Nature Reviews Neuroscience paper and several popular press interviews [a, b] that resulted.

[2] Aside from an in-house editor at F1000, Corey Bohil (a colleague from my time at the MIND Lab) was also gracious enough to read through and offer commentary.

[3] Hunter, J.   Post-publication peer review: opening up scientific conversation. Frontiers in Computational Science, doi: 10.3389/fncom.2012.00063 (2012) AND Tscheke, T.   New Frontiers in Open Access Publishing. SlideShare, October 22 (2013) AND Torkar, M.   Whose decision is it anyway? f1000 Research blog, August 4 (2014).

[4]  By opening up of peer review and manuscript publication, scientific discovery might become more piecemeal, with smaller discoveries and curiosities (and even negative results) getting their due. This will produce a richer and more nuanced picture of any given research endeavor.

[5] Mandavilli, A.   Trial by Twitter. Nature, 469, 286-287 (2011).

[6] One high-profile "discovery" (even based on flashes of brilliance) can take anywhere from years to decades, with a substantial period of interpersonal peer-review. Most scientists keep a lab notebook (or some other set of records) that document many of these "pers.comm." interactions.

[7] Sometimes, venues like F1000 can be used to feature attempts at replicating high-profile studies (such as the Stimulus-triggered Acquisition of Pluripotency (STAP) paper, which was published and retracted at Nature within a span of five months).


August 18, 2014

Maps, Models, and Concepts, August edition

Walcome back, Maps, Models, and Concepts series! In this edition, with content cross-posted to Tumbld Thoughts, we take a tour of Artificial Intelligence reconsidered (I) and the visualization of Economic History (II). Enjoy!


I. Can you haz intelligent behavior, internet bot?


Here are a few recent readings on the modeling and simulation of intelligence, broadly defined. The first two [1, 2] are part of a series by Beau Cronin on alternative ways to model intelligence. How do we produce "better" (e.g. more intuitive, or more human) artificial intelligence? Perhaps it is the model that counts, or perhaps it is the definition of intelligence itself. 

COURTESY: Figure 3 in [3].

The authors of [3] take the former view, and present a review on how various computational architectures can produce intelligent outputs. One example demonstrates how hierarchical Bayesian models (HBMs) can be used to acquire intuitive theories for various knowledge domains. But one can also use biologically-based architectural models to produce intelligent behavior. In [4], it is shown that fabrication and cell culture techniques can produce outputs similar to purely computational connectionist models.

COURTESY: Figure 2 in [4].


II. Did it begin with a bang, a boom, or a bust?


Aha! The moment of economic creation was not at 1650 after all! Conventional economic theory sometimes gives the impression that economists are creationists in spirit. Many historical graphs [5] only offer useful information back to the year 1650. Around 1650 or so, most economic indicators enter their exponential phase, which renders graphical information about previous eras incomparable.


But economist and modeler Max Roser [6] offers a historical view of global GDP going back 2,000 years. His "Our World in Data" website is an attempt to characterize global economics and other social phenomena as a series of visualizations. This includes maps (spatial distributions) and charts that make long-term comparisons more than a series of bad graphs. If John Maynard Keynes were to look at these data, he might say: in the long run, we are all wealthier [7].


NOTES:
[1] Cronin, B.   In search of a model for modeling intelligence. O'Reilly Radar blog, July 24 (2014).

[2] Cronin, B.   AI's dueling definitions. O'Reilly Radar blog, July 17 (2014).

[3] Tenenbaum, J.B., Kemp, C., Griffiths, T.L., and Goodman, N.D.   How to Grow a Mind: Statistics, Structure, and Abstraction. Science, 331, 1279-1285 (2014).

[4] Tang-Schomera, M.D., White, J.D., Tien, L.W., Schmitt, L.I., Valentin, T.M., Graziano, D.J., Hopkins, A.M., Omenetto, F.G., Haydon, P.G., and Kaplan, D.L.   Bioengineered functional brain-like cortical tissue. PNAS, 10:1073/pnas.1324214111 (2014).

[5] The bottom three pictures are courtesy of: Roser, M.   GDP Growth Over the Very Long Run. Our World in Data (2014).

[6] Matthews, D.   The world economy since 1 AD, in a single chart. Vox blog, August 15 (2014).

[7] Based on the quote "in the long run, we are all dead".

July 6, 2014

Carnivals and Toy Models

Two items of business (blog carnival and new paper announcements) in this post, neither of which involve carnival toys or any variant thereof. But keep reading anyway.

Nothing to see here. Move along.

Carnival of Evolution #73:

 
Time for another Carnival of Evolution. In this edition (#73) hosted by Pleiotropy blog, the theme is a tournament-style presentation based on the ongoing World Cup. This month’s Synthetic Daisies submission lost a close one early, and you will have to read CoE 73 to know who won the whole thing. Thanks go to BjornOstman for all of his work and the clever theme. Have an evolution-related blog post that needs publicizing? Please submit it to the CoE Facebook page.


Alicea, B. and Gordon, R.   Toy models for Macroevolutionary Patterns and Trends, Biosystems, 122, 25-37.


I invite you to take a look at a new paper by myself and Richard Gordon called "Toy Models for Macroevolutionary Patterns and Trends", out now in the journal Biosystems [1]. This will eventually be part of a special issue called "Patterns of Evolution". There is also a Github repository, which will house examples of toy models and other supplemental information. The paper reviews and/or describes 13 toy models, some pre-existing and others brand new examples. Toy models are representations that are intentionally oversimplified, used to approximate overarching trends while at the same time being sensitive to evolutionary context.

 The coupled avalanche model, an example of a macroevolutionary toy model.

We introduce 13 different toy models that cover a range of macroevolutionary phenomena such as the generation of diversity, the representation of lineages, and nonlinear evolutionary changes. There is also an undercurrent of meta-theory and why that is important to evolutionary theory-building.

The paper also provides examples of application domains, such as Artificial Life simulations and the analysis of high-throughput data. Toy models can also be used in tandem to approximate difficult evolutionary problems. While I do not want to give away too much of the details, I will say that the paper should prove useful to hard-core biologists, evolutionary modelers, bioinformaticians, and philosophers of science alike.

[1] the link provided might lead you beyond the Great Wall of Rentier. If you need a copy, e-mail me.


January 30, 2014

Fitting the Science to the Hype

This is a response to a recent article in Forbes by Steve Kotler [1], co-author of the book "Abundance" and techno-optimist. Even though it is intended as a blue-sky vision of an emerging technology, it also suffers from something I will call "fitting science to hype" [2], which happens a lot in media coverage of emerging technologies. That being said, I had a number of problems with this article, from its provocative title to its conclusions.

COURTESY: Shutar.

Point 1: It is actually inconclusive as to whether or not video games are addictive, at least in the same way as heroin. They may be addictive in the sense that a person prone to addictions will use video games as an addiction, but that is putting the cart before the horse (in a causal sense). To start off with this premise, and then build an argument off of this "self-evident truth" using an array of neurochemical facts (but not directly relevant evidence) is a bit misleading.

Point 2: The idea that "video games causes dopamine stimulation, therefore they are addictive" is likewise misleading. Aside from being a basis of addictive experiences, dopamine is also a very general signaling molecule for behavioral motivation. For example, dopaminergic signaling serves as the basis for economic transactions (e.g. rewards), so generalizing this to addiction is a large step indeed. Can we say then that because they are tightly associated with increases in dopamine, virtual environments will necessarily become essential economic tools? Probably not.

Dopamine machines, or dopaminergic-friendly activity (so to speak)? For more on the potential addictive aspects of financial trading and risk-taking, see [3].

Point 3: Video games are indeed dopamine-production machines. So are sports cars, jet skis, motorcycles, and guns. I'm not quite sure that one could make the argument that sports cars and jet skis cause the dopaminergic excesses associated with addiction. Aside from the dodgy reasoning of "machine-therefore-dopamine-therefore-addiction", human variation is an important determinant of addiction [4].

But the real problem here is that there is no null hypothesis to compare against. For example, the logical extreme of this argument would be that video games are always addictive. This, of course, would sound foolish. A proper way to disentangle this would be to look at dopamine production across the process of addiction, and then compare this with dopamine production in people who play video games but do not become addicted to them.

Point 4: Why will the our current lack of knowledge regarding how to control neurochemistry change? And why would we want to create virtual world addicts? This is how the sixth paragraph reads to me. There are areas of research such as Augmented Cognition [5] and allostatic regulation [6] and that would be relevant here, but alas nothing was discussed.

Addiction in the context of allostasis and allostatic load. COURTESY: Figure 5 in [6].

Point 5: As a source of explaining addiction as a result of over-allotted human cognition, Kotler's use of flow theory is oddly seductive. It allows for a higher state of awareness during focused activities (e.g. a magical mechanism) to be substituted for what is not well-known about cognitive processes like multisensory integration, attention, and memory. Or perhaps there is a selective interface between, say, flow and attention which allows for some "super" response. In any case, this is a unique form of inductive brain science, the ultimate result of which will be more questions than answers.

While this might be a bit of positivist bias on my part, it is worth keeping in mind that flow always needs to be rigorously defined in its application. Paragraph eight provides an example: the claim is made that flow results in (or from, which is not clear) an extremely potent neurochemical cocktail. This mimics a rapid hit of illicit drugs, and flow itself is the source of intrinsic motivation. A claim like this makes the direction of causality (e.g. enhanced neurochemistry result in flow, or flow results in enhanced neurochemistry) quite important.

Point 6: When I see the words "Moore's Law", I reach for my gun. Or my keyboard to protest. This is not an issue of too much dopamine production, but an issue of gross overuse. In any event, it's almost certain that Moore's Law does not apply here, as what is needed to understand the effects of video games on brains are better models to interpret the neurological data, not increasingly greater amounts of data on its own.


I think the idea of deep embodiment, while well-placed in this article, also masks the magnitude of challenges inherent in this type of work. From my own work, I would predict that deep embodiment might only be achieved through the use of a multivariate, closed-loop interface. Closed-loop control allows for entrainment between the environment and physiological dynamics.

The substrate involved with the setting of physiological state includes many moving parts, including nonlinear control components such as delays and superadditive responses. So take the latest hyperrealistic video game title. A human might experience deep embodiment for awhile as their physiology learns the intensity of the experience. This is a proto-learning that is similar to a more generalized plastic response. Yet, as with all forms of learning, there will be diminishing returns and acquisition will saturate. Thus, the person will adapt over time.

While one could say the person has been "sensitized" to the virtual environment, in reality we are witnessing a form of accomodation (complex as it is) mimicking the effects of addiction. Unless the person is explicitly trained, there will be a large effect between sensory performance in the real versus virtual world.

A model of brain-VR interactions without the pretense of parsimony.

UPDATE (3/1/2014): Here is a new paper [7] on the neural correlates of internet addiction. Given individuals who are identified as addicted to the internet, neuroimaging reveals the brain structures associated with addictive stimuli.

Neural Correlates of Internet Addiction. COURTESY: Figure 1 in [7].

NOTES:
[1] Kotler, S. and Edwards, L.A.   Legal Heroin: is virtual reality our next hard drug? Forbes, January 15 (2014).

[2] Fitting the science to the hype (or putting hype before the data) is much like putting models before the data, except that hype resembles an intentionally distorted model. On RationalWiki, this type of hype before the data is classified as "Science Woo". While I would not go that far, blue-sky hype is always something to be skeptical about.

[3] Coates, J.   The Hour Between Dog and Wolf. Penguin Books. YouTube video (2012).

[4] Volkow, N.D., Wang, G.J., Fowler, J.S., and Tomasi, D.   Addiction circuitry in the human brain. Annual Reviews in Pharmacology and Toxicology, 52, 321-336 (2012) AND Kuss, D.J.   Internet gaming addiction: current perspectives. Psychological Research and Behavioral Management, 6, 125-137 (2013).

[5] Schmorrow, D. and Fidopiastis, C.M.   Foundations of Augmented Cognition. Lecture Notes in Computer Science, Volume 8027 (2013).

[6] Koob, G.F. and Le Moal, M.   Drug Addiction, Dysregulation of Reward, and Allostasis. Neuropsychopharmacology, 24, 97-129 (2001).

[7] Gallinat, J. and Kuhn, S.   Brains online: structural and functional correlates of habitual Internet use. Addiction Biology, doi:10.1111/adb.12128 (2014).

October 22, 2013

Fireside Science: The Consensus-Novelty Dampening

This content is being cross-posted to Fireside Science. NOTE: this content has not been peer-reviewed!


I am going to start this post with a rhetorical question: why do people often assume that traditional (or common sense) practices are inherently better, even when the cumulative evidence is inconclusive? In discussing political and economic policy-making, Duncan Black and Paul Krugman uses the term "very serious people" (VSPs) [1] to describe important people who back positions that sound serious but are actually wrong-headed and perhaps even dangerous. Part of this "seriousness" stems from appealing to their own authority or broad issues that have always been a legitimate concern.

Recently, such a "very important person" (not a famous scientist, but a VSP in spirit -- and you will see why as we move along) has published an article in Science called "Who’s Afraid of Peer Review?" [2]. This paper involved a experiment to validate quality control in peer-review in open-access journals, and had some useful results that did not particularly surprise me. For example, open-access journals that send out copious amounts of spam encouraging submission of your work may not be reject papers with faked data in them.

To recap the experiment, the author generated a large number of scientific papers with scientific-sounding (but false) results with accompanying bad graphs. The generative model used here is similar in concept to the Dada Engine [3], and the experimental treatment could best be described as 1,000 (or more) Sokal hoaxes. The papers were sent out to the many open-access journals that have popped into existence in the past 15 years, with a fair number of acceptances. There were also many rejections, most notable rejection from PLoS One, perhaps the flagship open-access journal [4].

These data speak for themselves, or do they? HINT: beware of obvious answers offering gifts..... 

There are a number of problems with this article, least of which that it does not distinguish between predatory open-access journals and more reputable ones [5]. But perhaps the real problem with Bohannon's article is that it does not explore: 1) the role of lax editorial standards at traditional peer-review journals, or 2) conceive of this as a problem of false positives rather than a moral failing. This is along the lines of Michael Eisen's (founder of PLoS One) chief criticism with the article [6], and the reason why publication in Science makes it seem a bit like subterfuge.

Eisen's other criticism involves the Science article being biased against open-access. I read the article this way as well -- the moral imperative is quite thinly-veiled. The paper takes the tone of a reactionary pundit who thinks a return to traditional norms (perhaps even imagined ones) can solve any social problem. In light of this, here is some vitriol from Michael Eisen on the problem with subscription publishers vis-a-vis this issue:
"And the real problem isn’t that some fly-by-night publishers hoping to make a quick buck aren’t even doing peer review (although that is a problem). While some fringe OA publishers are playing a short con, subscription publishers are seasoned grifters playing a long con. They fleece the research community of billions of dollars every year by convincing them of  something manifestly false – that their journals and their “peer review” process are an essential part of science, and that we need them to filter out the good science – and the good scientists – from the bad. Like all good grifters playing the long con, they get us to believe they are doing something good for us – something we need. While they pocket our billions, with elegant sleight of hand, then get us to ignore the fact that crappy papers routinely get into high-profile journals simply because they deal with sexy topics"

Which one of these is not like the other two? HINT: the guy (on the left) who violated Copyright law. HYPOTHESIS: Open-access is not a crime. COURTESY: Time Magazine cover.

From a phase space (e.g. parametric) perspective, the problem may be that traditional peer review is a sparse sampling of quality control. Of all the possible gatekeepers, we have 3-4 people either chosen at random or chosen explicitly to prime the pump (NOTE: when you suggest reviewers, you prime the pump). Not exactly the kind of strict consensus defenders of the traditional gatekeeper model like to believe exists.

A related observation (also inspired by physics) is something I call the "bifurcating opinion" issue. This occurs more often than one would think (or hope for). For example, one reviewer thinks an article is great, while the other reviewer hates it. The solution might be to add reviewers, but this might simply extend the problem in a manner similar to flipping a coin. Is this a legitimate way to reach consensus on quality control? Or is consensus even necessary?

I will now tell a story about a manuscript I posted [7] to Nature Precedings, a preprint (now archival) service run by a traditional publisher, in 2009. The paper was accepted under limited standards of quality control (there is a screening process, but no formal peer review process). I did so for two reasons: 1) a belief in scientific transparency, and 2) it did not fit cleanly into any existing journal (based on my first-pass approximation of the journal landscape). Soon after posting the paper, I was contacted by a Journal editor, who encouraged me to submit the paper to their Journal (which I did).

Three months later, the editor contacted me and said that 45 reviewers felt they could not be impartial reviewers to the article. So at least my intuitions were vindicated! But what does this say about quality control? Most certainly, the reviewers were not willing to issue a false positive acceptance. But does this come at the expense of rejecting novelty (a false negative)?

A schematic showing a 3-D phase space (demonstrating examples of sparse sampling and bifurcating opinion) of scientific expertise for a given area of research/article. The phenomenon of bifurcating opinion was used to show that agreement amongst reviewers is expected at no better than a chance occurance by [8].

In an article from the Chronicle of Higher Education [9], it is pointed out that open-access journals are in a frontier (e.g. wild-west) phase of development. In that sense, a non-uniform degree of quality control should be expected across a random sampling of journals -- with some degree of predatory enterprise. A representative from Science said this about the results of [2]:
“We don’t know whether peer review is as bad at traditional journals,” he said. “Then again, OA is the growth area in scientific publishing.”
This brings up another issue: does selectivity necessarily reflect quality? In the Bohannon study [2], open-access accepted the fraudulent papers even after they were put through peer-review process. As far as I am aware, the qualitative responses of these reviewers were not considered as a factor in the acceptance of fraudulent articles.

Journals with high selectivity are widely assumed to be better at filtering out noise (e.g. weak results and methods) and potential fraud. However, as long as the rejection rate (100-acceptance rate) exceeds the number of fraudulent manuscripts, selectivity and fraud (or error) detection tend to be two seperate things. Sure, journals with a low acceptance rate are likely to include fewer fraudulent papers. But these same journals will also tend to reject many reasonable, and sometimes even outstanding papers.

It is notable that retractions of papers from highly-selective journals are not that rare. Take the case of Anil Potti, whose data were discovered to be fabricated. The result (as of 2012) is 11 retractions, 7 corrections, and 1 patrtial retraction [10]. Only 2 of these retractions involved an open-access journal (PLoS One). The rest, in fact, involved peer reviewed biomedical journals.

A classification scheme for Type I (B -- or a false negative) and II (C -- or a false positive) error in manuscript evaluation. The goal of peer review should be to minimize the number of manuscripts in categories B and C. Of course, this is not considering manuscripts rejected for non-fraudulent reasons.

What are potential solutions to some of these problems [11]? Particularly, how can we keep selectivity from stifling innovation (e.g. novel interpretations, groundbreaking findings)? Can the concept of crowdsourcing provide any inspiration for this? John Hawks [12] discusses radically-open peer review as done by F1000. The F1000 model operates on the premise of the popularity. The more votes an article gets, the more staying power the article has.

But should popularity be linked to significance and/or quality? Investigations into the incongruity between popularity and influence suggests that these should be decoupled [13]. Or put another way: is it the percentage of accepted manuscripts that makes a quality journal, or is it that all articles meet certain benchmarks? And if the acceptance criterion is the only acceptable measure of quality, then is it an unfortunate one that stifles innovation [14].

Here's the deal: you give me $1,000, and I'll give you legitimacy, or you pay me a subscription fee, and I'll give you even more legitimacy....... COURTESY: South Park, Scott Tenorman Must Die.

So are there legitimate issues of concern here? Of course there are. But there are also pressing problems with the status quo that are for some reason not as shocking. Fooling people with non-sequiturs and supposedly self-evident experimental design flaws is a clever rhetorical device. But it does not answer some of the most pressing issues in balancing academic quality control with getting things out there (e.g. reporting results and scientific interaction) [15]. In the spirit of non-sequiturs, I leave you with a video clips from Patton Oswalt's TED talk highlighting the lack of quality control in the motivational speaking industry.

Still image from the Patton Oswalt TED talk, which parodied motivational speaking by generating nonsensical passages using the generalized motivational schema (e.g. sentence styles, jargon).

NOTES: 

[1] For more, please see: Black, D.  Everything Liberal Activists Do Is Wrong and Destructive. Eschaton blog, July 30 (2010) AND Krugman, P.  VSP Economics. The Conscience of a Liberal blog, May 7 (2011).

[2] Bohannon, J.   Who’s Afraid of Peer Review? Science, 342, 60-65 (2013). The reason I make this judgmental statement is because it is important to distinguish between legitimate skepticism and fostering a moral panic (e.g. open-access is bad for science, and I'm going to use the organ of a major journal to foster support of the cause). I feel that Bohannon has crossed this line.

For a more nuanced take on the phenomenon of predatory open-access journals, please see: Beall, J. "Predatory" Open-access Scholarly Publishing. The Charleston Advisor, April (2010).

[3] the modeling of non-sequiturs that resemble a particular field's jargon (e.g. legalese, postmodernism) using a recursive transition algorithm. For more on the Dada Engine, please see: Bulhak, A.  On the Simulation of Postmodernism and Mental Debility Using Recursive Transition Networks. CiteSeerX repository (1996).

[4] I have a confession: I was rejected from PLoS One! However, this might not be as "bad" as it sounds, if these two references are correct:

a) Neylon, C.   In defence of author-pays business models. Science in the Open blog, April 29 (2010).

b) Anderson, K.   PLoS’ Squandered Opportunity — Their Problems with the Path of Least Resistance. The Scholarly Kitchen blog, April 27 (2010).

[5] Hawks, J.   "Open access spam" and how journals sell scientific reputation. John Hawks weblog, October 3 (2013).

Of course, conventional journals also rely on the same sense of reputability, whether deserved or not. For more please see: Reich, E.S.   Science publishing: the golden club. Nature News, October 16 (2013).

[6] Eisen, M.   I confess, I wrote the Arsenic DNA paper to expose flaws in peer-review at subscription- based journals. It is NOT Junk blog, October 3 (2013).

Since the Bohannon article deals with a competing publication model, Science should have at least issued a conflict-of-interest disclaimer upon publication. As the Wikipedia cleanup editors would say: this article sounds like an advertisement.

[9] Basken, P.   Critics Say Sting on Open-Access Journals Misses Larger Point. Chronicle of Higher Education, October 4 (2013).

[10] Ivanoransky   The Anil Potti retraction record so far. Retraction Watch blog, February 14 (2012).

* or simply Google the names "Yoshitaka Fujii" and "Joachim Boldt" -- their retraction count is astounding.

More insight might be found in the following paper: Steen, R.G., Casadevall, A. and Fang, F.C.   Why has the number of scientific retractions increased? PLoS One, 8(7), e68397.

[11] For a visionary take (written in 1998 and using National Lab pre-print servers as a template for the future) on open-access publishing, please see: Harnad, S.   The invisible hand of peer review. Nature Web Matters, November 5 (1998).

* this reference also discusses self-policing vs. peer consensus and the issue of peer review as a popularity poll.

[12] Hawks, J.   Time to trash anonymous peer review? John Hawks weblog, October 3 (2013).

[13] Solis, B.   The Difference between Popularity and Influence Online. PaidContent, March 24 (2012).

[14] I was once told that to be accepted for publication, a scientific article should not have too many novelties in it. For example, an article that has a novel theoretical position or method is okay, but not both (or additional novelties). This was anecdotal -- however, this seems to be a built-in conservative bias of the peer-review system.

UPDATE (11/5)! What is the optimal level of novelty relative to scientific impact? For a large-scale analysis, please see: Uzzi, B., Mukherjee, S., Stringer, M., and Jones, B.   Atypical Combinations and Scientific Impact. Science, 342, 468-472 (2013).

[15] Food for thought: does peer-review and standards actually harm science by excluding negative results from the literature? For more about this and the replicability crisis in science, please see this article (which I will be coming back to in a future post): Unreliable research: trouble at the lab. Economist, October 19 (2013).

Printfriendly